AI’s New Price War
THE CDO TIMES | AI ECONOMICS
When capable models become free, who captures the value?
By Carsten Krause, CDO TIMES
Open-weight models and falling inference prices are changing the economics of AI. The strategic question for executives is no longer simply which model is smartest, but where cost, control, reliability, and business value meet.

The model market is shifting from scarce intelligence toward a wider supply of capable alternatives.
The price of intelligence is moving faster than the market expected
The AI market spent its first phase selling access to scarce capability. A small group of providers trained the most capable models, hosted them behind APIs, and charged customers for each million input and output tokens. That model still matters, especially for complex reasoning, multimodal work, and high-stakes reliability. But the economics are changing as open-weight models become more capable and inference prices fall. The result is a price war over machine-generated intelligence, and the consequences reach far beyond a developer’s API bill.
Stanford’s 2025 AI Index estimated that the cost of querying a model at roughly GPT-3.5 benchmark performance fell from $20 per million tokens in November 2022 to $0.07 by October 2024, a reduction of more than 280 times. The same report found that inference prices had declined between nine and 900 times per year depending on the task. Those figures are not a forecast for every workload, and benchmark equivalence does not mean models are interchangeable in production. They do show that the price of a given level of capability can fall much faster than the price of a conventional enterprise software license. That changes procurement, product design, and the assumptions behind provider revenue.
At the same time, Stanford’s 2026 AI Index says U.S. and Chinese models have traded the lead multiple times since early 2025, and that as of March 2026 the leading Anthropic model was ahead by 2.7% on the index’s comparison. That is a narrow measured gap at the top of one evaluation, not proof that every model performs equally across languages, tasks, safety needs, or operating conditions. It does indicate that buyers have more credible alternatives than they did when one or two proprietary systems appeared decisively ahead. More credible alternatives give buyers leverage even when they continue to choose premium models. The competitive story is therefore not “open has won,” but “open and lower-cost alternatives have made the premium harder to defend without evidence.”
Tokenomics is about the cost of a completed job
Tokenomics is becoming shorthand for the economics of using AI at scale: the cost of producing, consuming, and managing tokens, and the revenue or business value those tokens help create. A token is a unit of text processing, not a unit of business value. Providers usually price input and output tokens differently, and may price cached inputs, reasoning tokens, tool calls, or longer context separately. A low price per million tokens can still produce an expensive application if the system repeatedly reasons, retrieves documents, calls tools, and retries. For leaders, the useful unit is often cost per successful task, resolved ticket, reviewed contract, or completed workflow.
This distinction matters because token counts can rise even as unit prices fall. An agent that plans, searches, checks its own answer, invokes a tool, and summarizes the result may use many more tokens than a short chat response. A workflow that produces more accurate outcomes could still be economically attractive, but only if the organization measures the value and includes the extra inference, orchestration, and oversight costs. Conversely, a cheap model that needs repeated correction can be more expensive than a pricier model that succeeds in one pass. The question is not simply how many tokens did we buy; it is how many useful outcomes did those tokens produce, at what total cost, and with what risk.
Inference prices can fall while total usage expands; both sides of that curve matter.
DeepSeek’s current API price sheet makes the new market pressure tangible: it lists its V4.1 Flash service at $0.30 per million input tokens on peak pricing when the prompt is not cached, and $1.20 per million output tokens, with off-peak prices half those amounts. These are prices for a hosted API service, not proof that a self-hosted copy has zero operating cost or that every vendor’s service is directly comparable. They are also subject to change, as DeepSeek itself states on the pricing page. But they put a visible low-cost reference point into enterprise negotiations. Providers now have to explain the incremental value that justifies their price, not rely on buyers having no realistic option.
“Open source” often means open weights, and that distinction has business consequences
The market often uses “open-source model” as a catch-all, but the label can hide meaningful differences. The Open Source Initiative’s Open Source AI Definition describes an AI system as including the model, parameters, inference code, and the information needed to study and modify it. In practice, many widely discussed releases provide downloadable weights while withholding some training data, training code, or other components. The OSI explicitly distinguishes open weights from fully open-source AI. Buyers should therefore read the license and technical materials instead of treating “open” as a complete description of their rights.
Meta’s Llama 4 Scout and Maverick are examples of models released with downloadable weights, but the release is governed by Meta’s community license and acceptable-use policy. Those documents, not the marketing shorthand, define the permitted uses and obligations. This does not make the release unhelpful; open weights can let a company run models in its own environment, fine-tune them, choose an inference provider, and reduce dependence on a single API. It does mean that legal review, deployment permissions, and the availability of training information remain part of the total cost of ownership. A model can be economically attractive and still carry constraints that matter to a particular company, product, or market.
That nuance also clarifies what “free” means. A company may download weights without paying a per-token license fee, but it still pays for compute, storage, engineering, monitoring, security, upgrades, and the people who operate the service. If usage is low or irregular, a metered API may be cheaper than reserving GPU capacity and staffing a private deployment. If usage is high, predictable, sensitive, or latency constrained, self-hosting or a managed open-weight endpoint may become attractive. The best answer depends on traffic shape, utilization, workload quality, and governance requirements, not ideology about open versus closed.
Why low-cost models pressure premium providers
Open-weight models pressure large providers through several channels at once. First, they give buyers a credible outside option, which weakens the ability to set prices without reference to alternatives. Second, they enable model routing: a company can send routine classification, summarization, extraction, or drafting to a smaller or cheaper model and reserve a frontier model for hard cases. Third, they support private deployments where organizations need greater control over data location, customization, or continuity. Each option makes it harder to sell every token at a premium rate.

Enterprises can rent intelligence through a hosted service or operate a model within their own environment.
The pressure can reach the whole AI value chain, but it will not affect every company in the same way. Model labs that depend heavily on usage-based API revenue face direct pressure on price and gross margin if customers shift suitable workloads elsewhere. Cloud providers may see lower revenue per token while still benefiting from greater overall demand for compute, storage, networking, and managed AI services. Chip suppliers may benefit if cheaper inference expands usage, although more efficient models can reduce the compute needed for any one response. The likely outcome is a redistribution of value across the stack, not a simple collapse in AI demand.
The growth in consumer and enterprise usage supports that more complex picture. Stanford’s 2026 AI Index reports that generative AI reached 53% population adoption within three years and estimates annual U.S. consumer value at $172 billion by early 2026. It also notes that consumers often use tools they access for free. Those figures describe adoption and estimated consumer value, not revenue that providers can automatically collect. They show why a zero-price interface can be commercially rational: free access can build distribution, usage, product feedback, and demand for premium or adjacent services. In a market where the marginal cost of a response is falling, control of the customer relationship may matter more than charging for every interaction.
What the leading providers can still sell
Large providers are not limited to defending a model’s raw token price. They can compete on frontier capability, dependable service levels, security controls, integrated tools, managed retrieval, observability, and support when an application fails. They can bundle models into productivity software, cloud platforms, developer tools, or agent frameworks, making the model one part of a larger paid service. They can also offer proprietary models for tasks where quality, speed, scale, or risk controls demonstrably reduce total operating cost. A premium remains viable when it is connected to an outcome the buyer values and can verify.
That response may change how AI services are priced. Flat subscriptions and bundled access can shift the buyer’s attention away from individual tokens, while usage tiers and service guarantees can monetize predictability and performance. Providers can also compete to lower their own unit costs through caching, batching, quantization, distillation, specialized chips, and model routing. The economics are familiar from cloud computing: falling cost per unit can expand total consumption, but customers increasingly expect efficiency gains to show up in the price they pay. Provider advantage will depend on whether lower cost creates enough new use, retention, and platform value to offset price compression.
A provider with a closed frontier model may still have a durable lead on difficult tasks, specialized data, product integration, or reliable operation. Yet that lead needs to be demonstrated by workload-specific evaluation, rather than assumed from a benchmark headline. Open models can be adapted to a company’s terminology and process, while closed models can offer stronger managed controls and less operational burden. Some organizations will rationally use both. The competitive position is likely to be won by portfolios and services, not by a single winner-takes-all model.
The matrix below describes strategic choices available to providers under price pressure. It is a market framework, not a claim that every provider currently uses every lever. Each option changes what the buyer is paying for and what the provider must prove. The strongest responses make value visible at the level of a customer outcome. Price cuts alone may protect share in the short term, but do not establish a durable reason to stay.
| Provider response | What the customer is buying |
| Premium frontier model | Higher success on difficult tasks, if workload tests show a material quality advantage. |
| Lower-cost tiers and model routing | More economical handling of routine volume with escalation for hard cases. |
| Bundled products, subscriptions, and platform services | A usable workflow, distribution, integrated tools, and managed infrastructure around models. |
| Enterprise controls and service guarantees | Security, support, predictable service levels, auditability, and lower operating burden. |
The executive decision is a portfolio decision
For enterprise leaders, the right question is not “Should we move everything to open models?” It is “Which workloads should use which model, through which operating path, under what controls?” Begin by grouping tasks by consequence, sensitivity, latency, volume, and tolerance for errors. Establish a representative evaluation set from real work, then compare model quality, answer consistency, throughput, response time, and cost per successful task. Include the work required to review and correct output, because those human costs can dominate the apparent token savings.
The following routing pattern is a starting hypothesis for evaluation, not a universal model prescription. Match a model to the task’s sensitivity, difficulty, and consequence, then test it with representative examples. Route routine, bounded work to lower-cost models when they meet the quality threshold. Keep a clear escalation path for uncertain or higher-consequence cases. Human accountability remains in place when an AI output informs a consequential decision.
| Workload pattern | Starting option to test | Decision check |
| High-volume, bounded extraction or classification | Small or low-cost hosted model; open-weight option if volume and controls justify it | Accuracy on a labeled sample; cost per accepted record. |
| Internal knowledge search and summarization | Managed model with retrieval, or privately deployed open weights | Permission-aware retrieval; citation quality; data handling. |
| Complex reasoning, coding, or ambiguous tasks | Premium frontier model, with cheaper-model fallback where tested | Task success, latency, consistency, and review burden. |
| High-consequence decisions | Model assistance only, with qualified human review | Escalation rules, audit trail, and accountable decision owner. |
Then calculate total cost of ownership across more than the API invoice. For a hosted model, include tokens, caching, retrieval, tool calls, retries, and any premium tier or network cost. For a self-hosted model, include accelerator capacity, utilization, power, hosting, engineering, deployment, monitoring, incident response, version upgrades, and license obligations. Account for idle capacity: a GPU reserved for peak demand may sit underused for much of the week. Compare the options over a realistic horizon, and run a sensitivity analysis for usage growth, model improvements, and price changes.
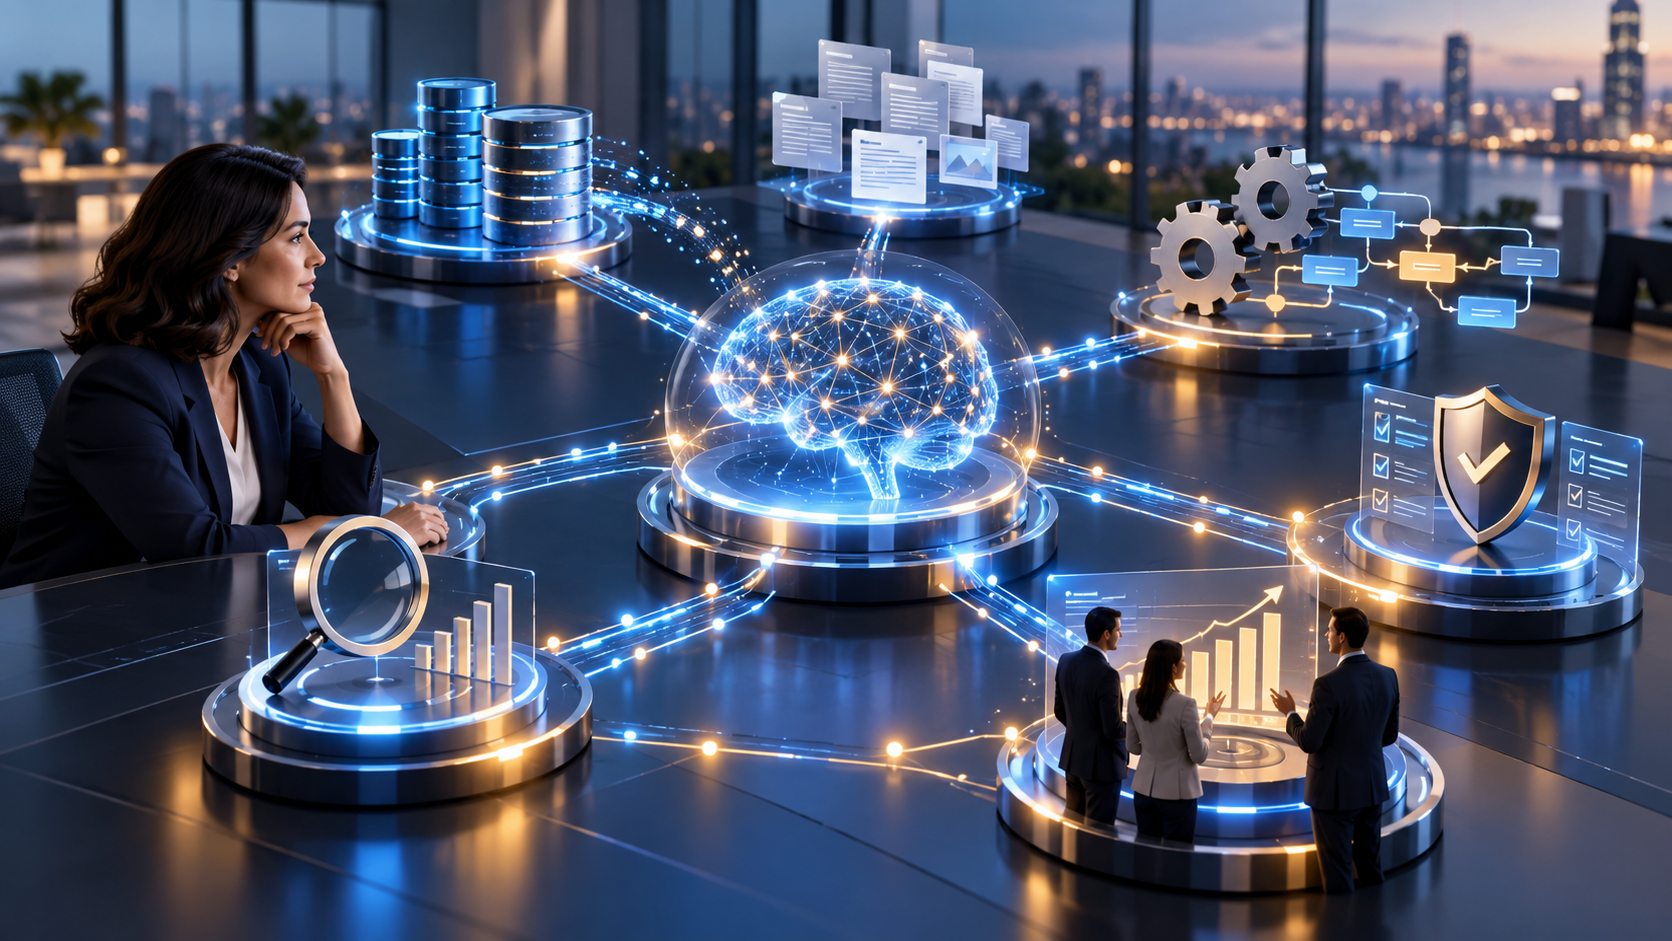
The model is one component in a wider system of data, workflow, governance, and measurable outcomes.
Governance should follow the workload, not the model label. A model downloaded to a private environment may reduce data exposure to an external API, but the organization still has to secure weights, protect prompts and outputs, test for vulnerabilities, and monitor behavior. An open-weight model may be modified in ways that remove safeguards, while a closed service may change its model or terms without the buyer controlling release timing. Legal teams should review license terms and provenance; security teams should address access, logging, and patching; and business owners should define who is accountable for the decision the system informs. The operating model is what converts a model choice into an enterprise capability.
The durable value moves into context, workflow, and trust
When several models can produce acceptable answers, differentiation shifts to the system around them. The quality and rights of the organization’s data matter because models need relevant context to produce useful work. Workflow design matters because it determines when the model acts, when a person reviews, and what happens when confidence is low. Evaluation matters because it shows whether a model actually improves a process after deployment. Governance matters because a low-cost output has little value if it creates an unacceptable legal, security, or operational exposure.
This does not make foundation models interchangeable commodities today. Capability continues to advance, and performance differences still matter across coding, science, languages, vision, tool use, and complex reasoning. Stanford’s 2026 report also warns that responsible-AI measurement and reporting have not kept pace with capability, while documented AI incidents rose to 362 in 2025 from 233 in 2024. An enterprise should not trade away controls or reliability for a lower token bill without testing the consequences. The better conclusion is that model cost is becoming one part of a larger decision about control, performance, and risk.
There is also a real debate over the risks of releasing powerful model weights. Anthropic’s July 2026 statement describes open weights as valuable for access, competition, and user control, while arguing that sufficiently capable systems may be harder to monitor or withdraw after release. That is a company’s stated position, not an independent verdict on all open models. It highlights a practical trade-off: decentralized access can widen innovation and user choice, while also shifting safety responsibilities toward deployers and the broader ecosystem. Enterprise adoption should weigh those benefits and responsibilities with the same discipline as cost.
The CDO TIMES Bottom Line
AI tokenomics is entering a new phase because capable models are becoming more abundant, more efficient, and less expensive to access. Open-weight releases intensify that shift by giving enterprises choices over where and how models run, while low-cost hosted APIs create a price benchmark even for buyers who never self-host. This puts larger providers under pressure to defend their premium with measurable capability, reliability, security, integration, and service. The market may still grow as prices fall, but more of the value will be contested across models, cloud platforms, infrastructure, and applications.
For executives, the mandate is to manage cost per successful outcome, not chase the lowest token price or an “open” label. Build a workload portfolio, benchmark it against real tasks, include operating and governance costs, and route each class of work to a model and service that fits its needs. Treat license terms, data control, and operational readiness as economic variables. The companies that win will be those that turn cheaper intelligence into trusted workflow improvements and customer value. When the model becomes easier to replace, the system around it becomes the strategy.
Sources and further reading
1. Stanford HAI, The 2025 AI Index Report — Research and Development: https://hai.stanford.edu/ai-index/2025-ai-index-report/research-and-development
2. Stanford HAI, The 2026 AI Index Report: https://hai.stanford.edu/ai-index/2026-ai-index-report
3. DeepSeek API, Models & Pricing: https://api-docs.deepseek.com/quick_start/pricing/
4. Open Source Initiative, The Open Source AI Definition 1.0: https://opensource.org/ai/open-source-ai-definition
5. Meta AI, The Llama 4 herd: https://ai.meta.com/blog/llama-4-multimodal-intelligence/
6. Meta AI, Llama 4 Community License Agreement: https://dev.meta.ai/llama/llama4/license
7. Meta AI, Llama 4 Acceptable Use Policy: https://dev.meta.ai/llama/llama4/use-policy
8. Anthropic, Our position on open-weights models (July 27, 2026): https://www.anthropic.com/news/position-open-weights-models